
Hello from Boston,
I hope you had an interesting and productive week.
Claude, when prompted, shared the following on the systems thinking lessons one can take from the mighty forests: “The mycorrhizal model implies that the most resilient organizations are not those with the best-managed hierarchies but those with the densest, most reciprocal informal networks — the relationships that don’t appear on any chart, where knowledge and help flow based on proximity and need rather than reporting lines. Every organization has this layer. Almost none of them tend it deliberately, measure it, or protect it during restructuring. When a company “right-sizes,” it cuts nodes. It rarely asks which nodes are holding the informal network together — and those are often not the ones with the largest titles. The forest doesn’t reorganize by redrawing the org chart. It reorganizes by changing what flows where. That’s a different theory of institutional change entirely.”
Take Note…watch for areas where we are messing with the ‘reciprocal informal networks’ as the 2nd and 3rd order effects can be devastating…
1 Getting Visual
2 If You Read One Thing Today - Make Sure it is This
3 Consequential Thinking about Consequential Matters
4 Big Idea
5 Big thinking
6 The Longer You Wait
1 Getting Visual
The Big Picture: The Journey - A look at how Economic Power shifted over 200 years: Over the last 200 years, economic leadership has shifted from China to the British Empire, then to the United States, and increasingly back toward Asia. In 1845, the British Empire, on which the sun famously “never set,” contributed nearly one-quarter (23.8%) of global GDP. World War II marked a turning point in global economic leadership. By 1944, the U.S. accounted for 29.7% of world GDP, the highest share reached by any economy in the modern period covered by this dataset. For centuries, China was a center of the global economy. Political instability and its failure to keep pace with European industrialization contributed to a long decline in its share of world GDP during the 19th and 20th centuries. Beginning in the late 20th century, economic reforms and China’s emergence as a global manufacturing hub helped it regain lost ground. By 2025, China accounted for 21.8% of world GDP, or more than one-fifth of the total.
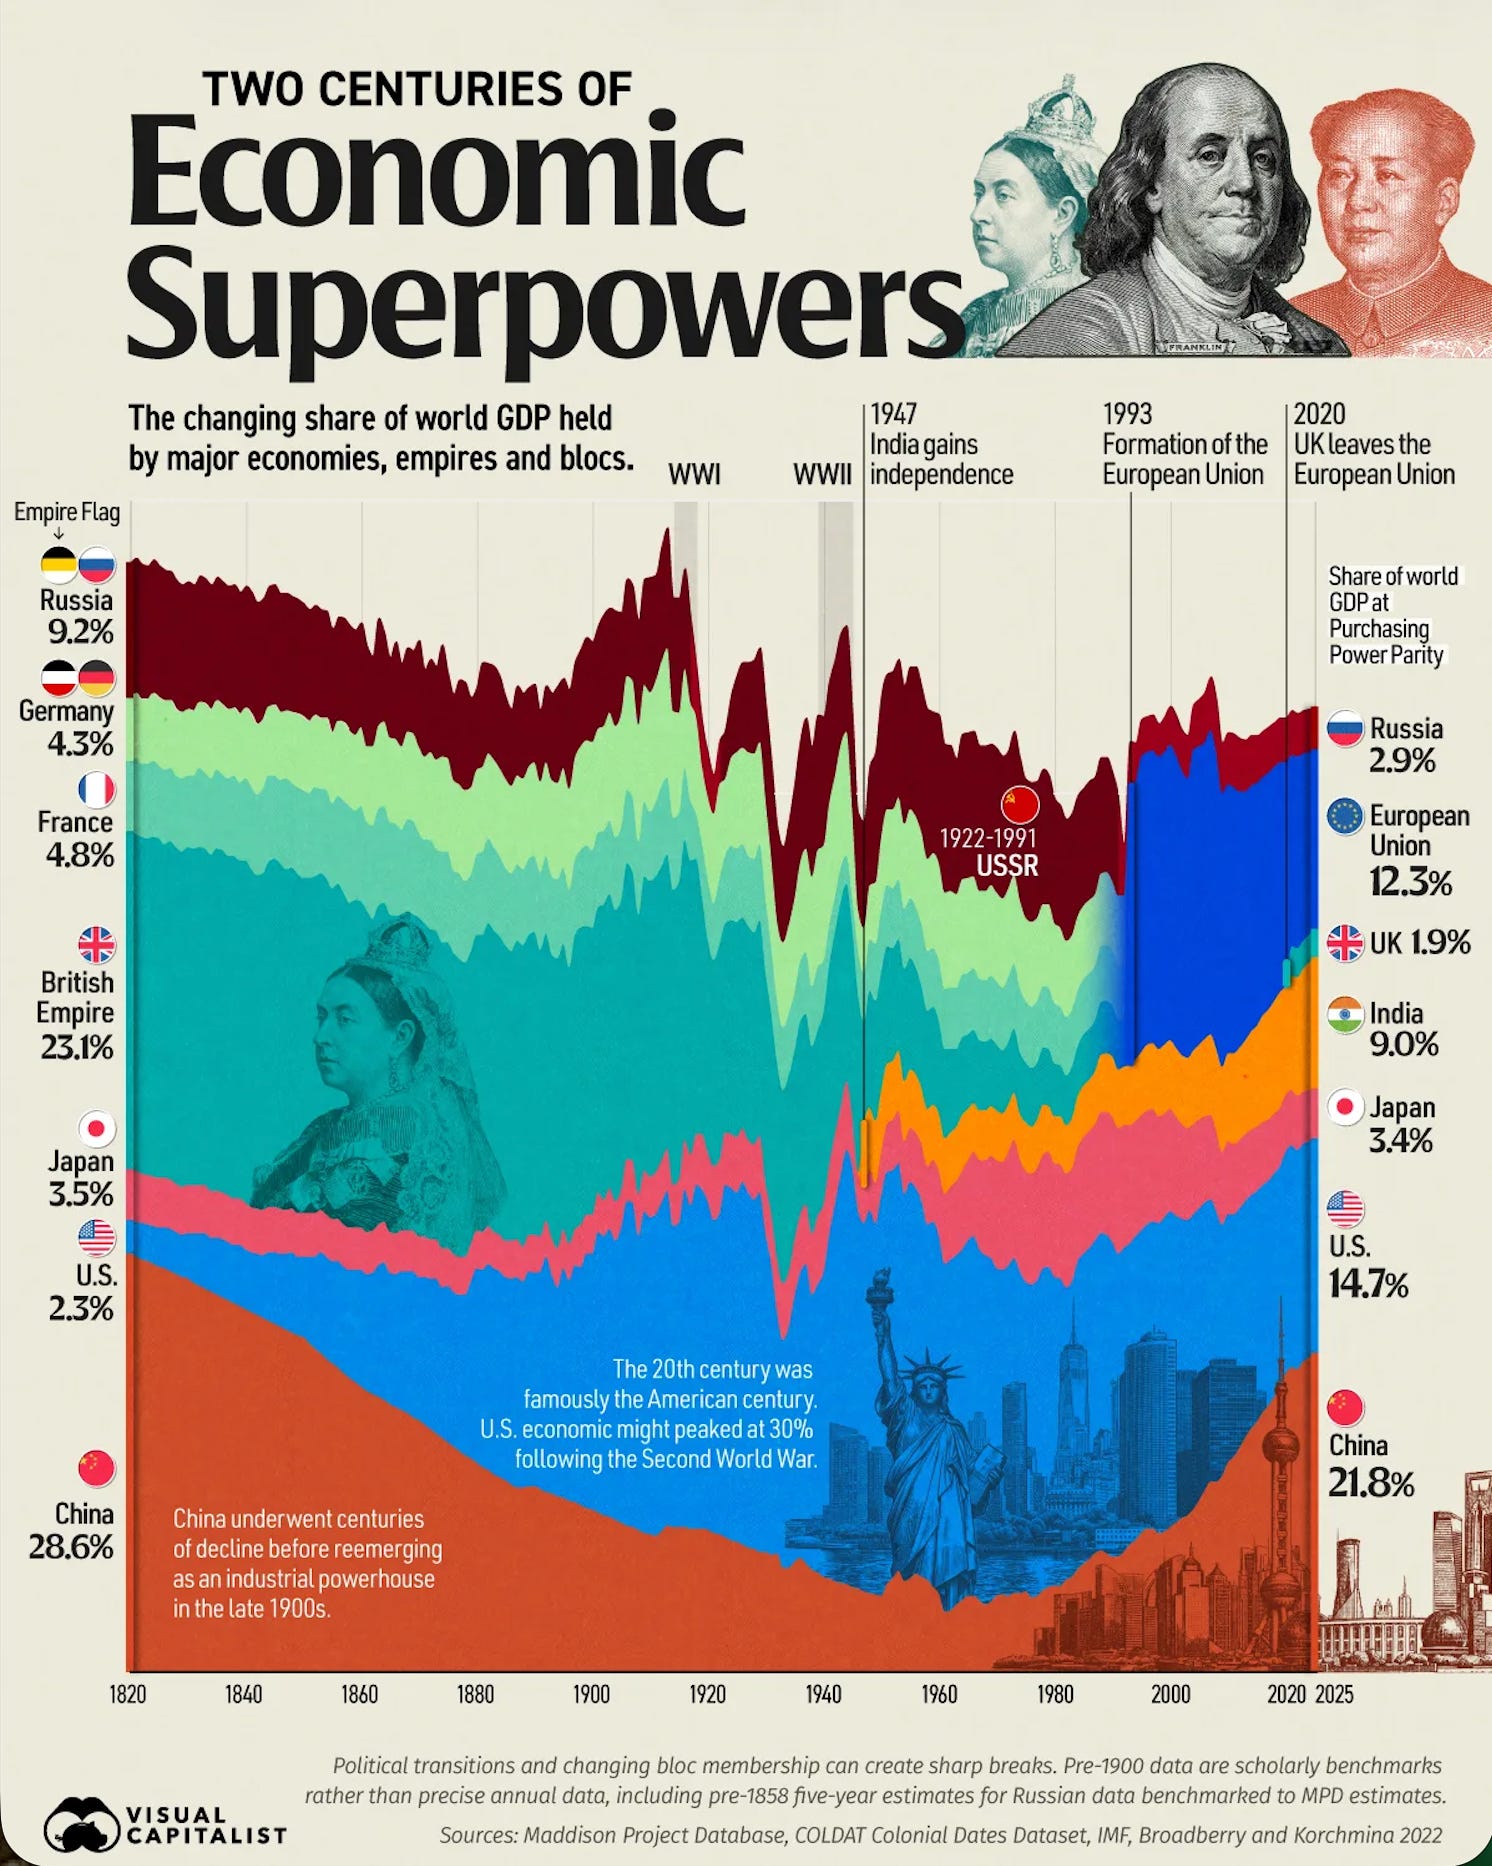
Learn more: https://www.visualcapitalist.com/how-economic-power-shifted-over-200-years/
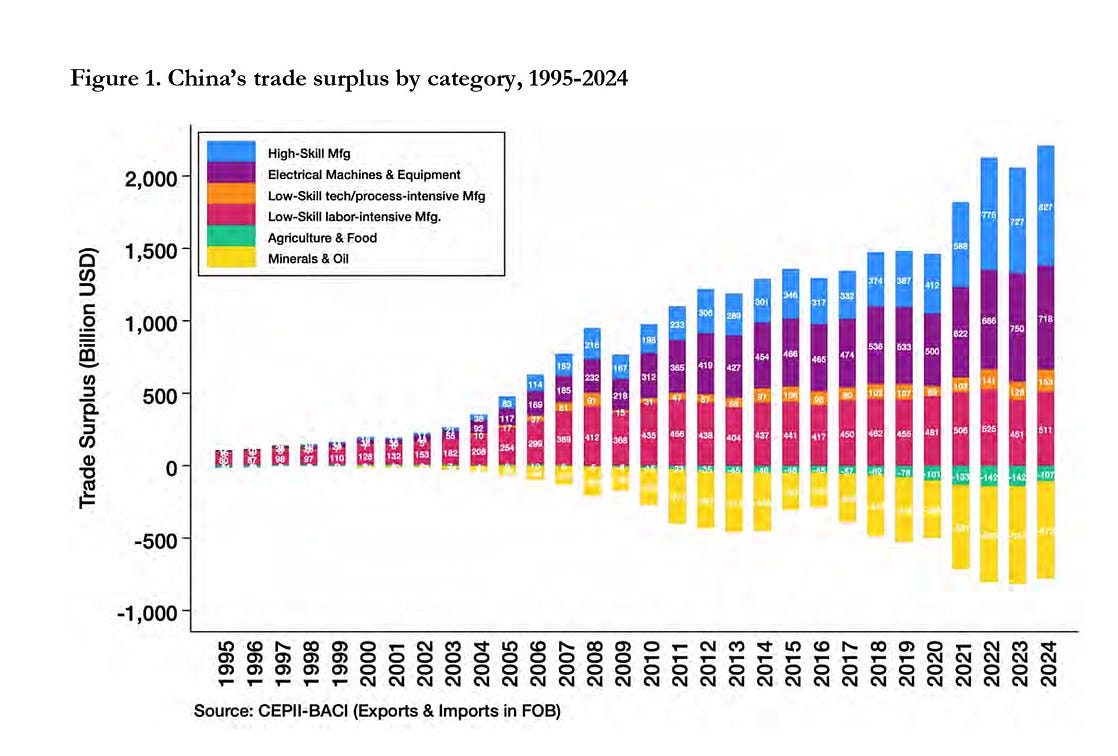
Spotlight: China’s economic rise has been built on manufacturing and increasingly on high-skill manufacturing at massive scale.
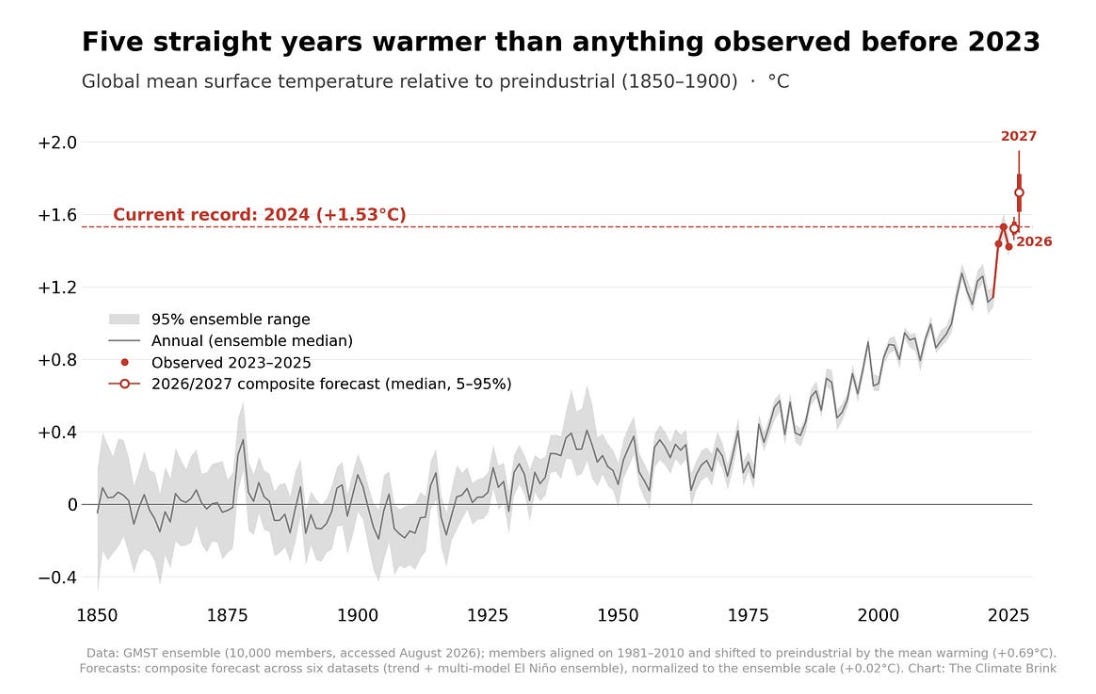
Big Picture - The Temperature rises. With the coming El Niño, climate scientists expect 2026 and 2027 to see record-high temperatures.
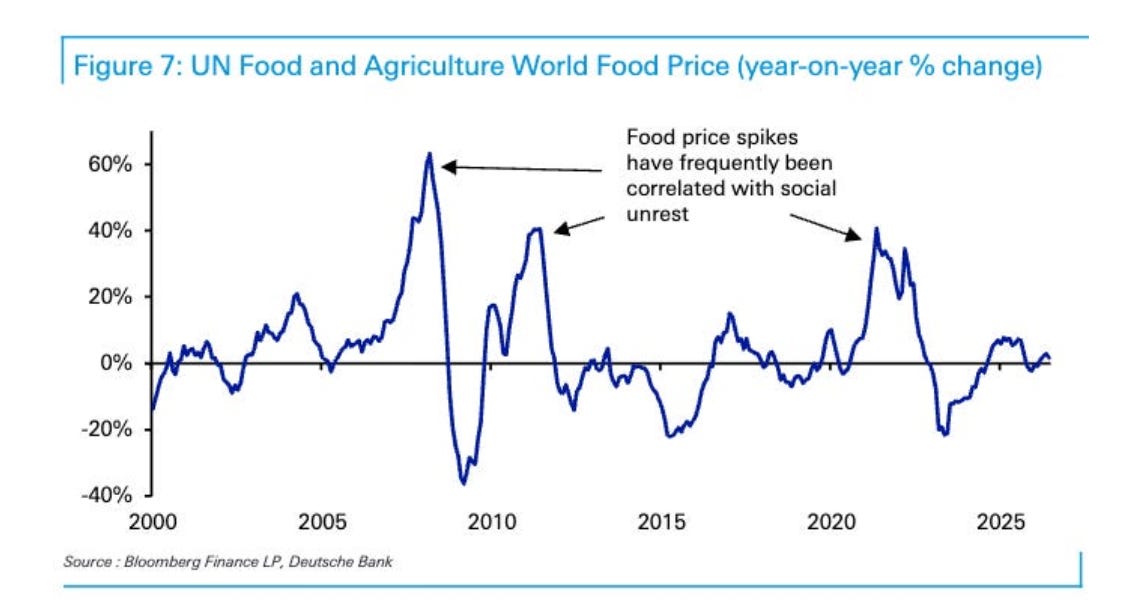
Big Picture - The climate related risks have real economic effects. El Niños have historically intensified social unrest via food and energy supply shocks – unrest periods are closelycorrelated with food price spikes of 40-60% YoY.
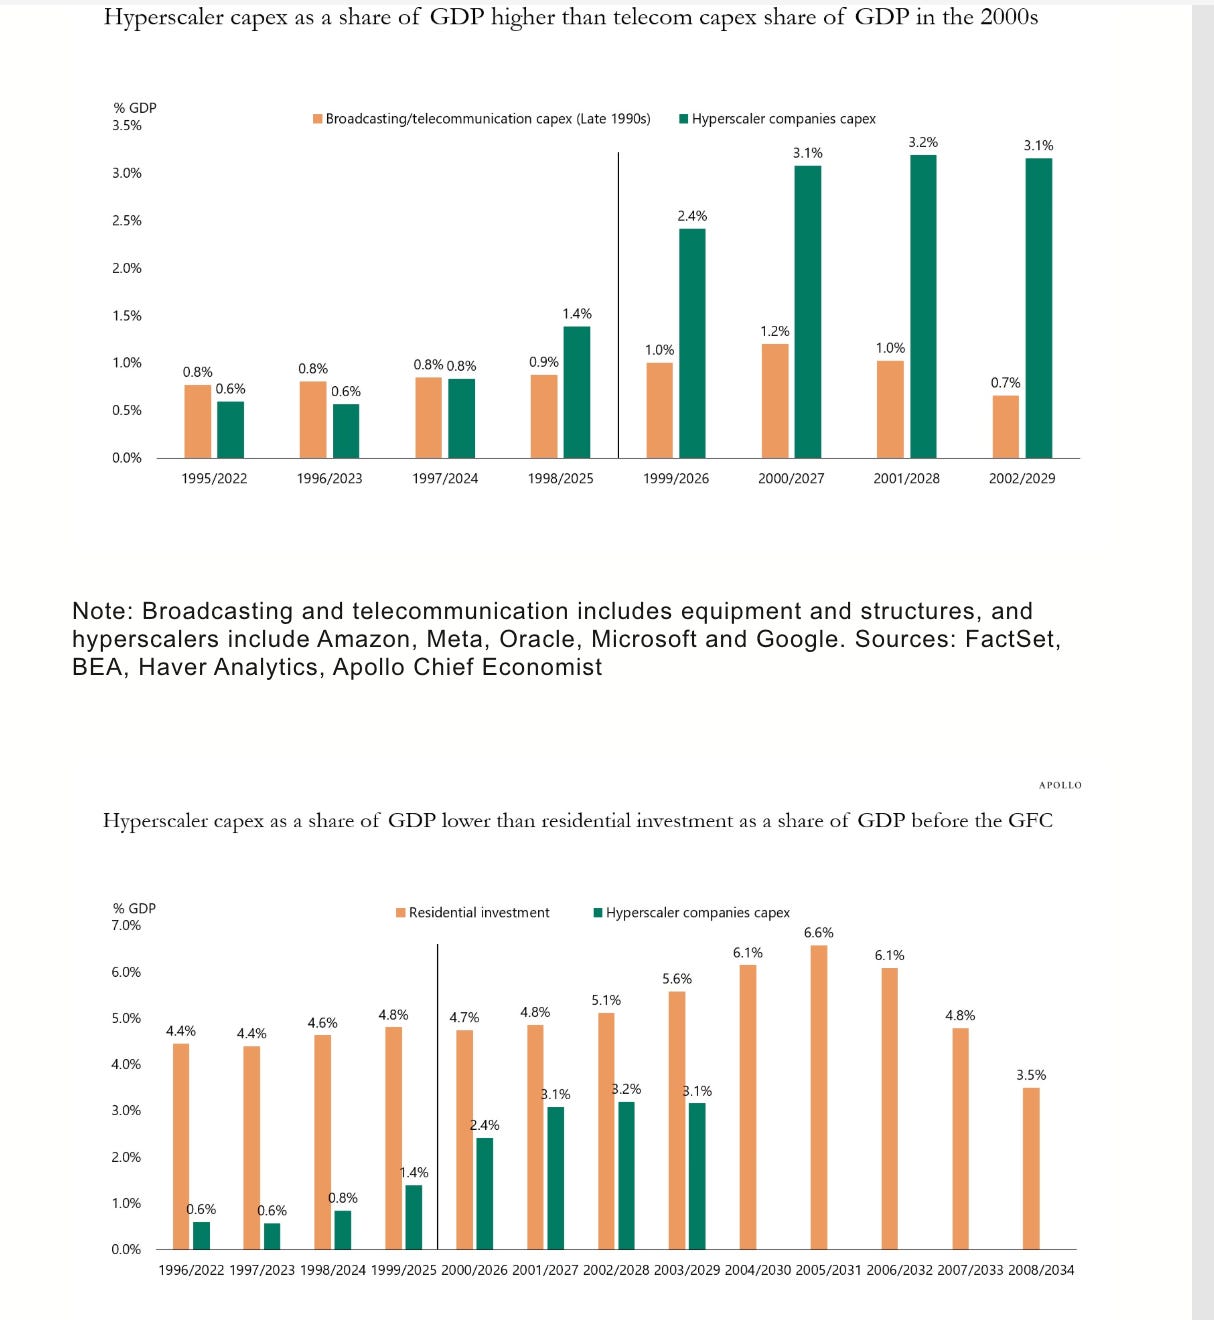
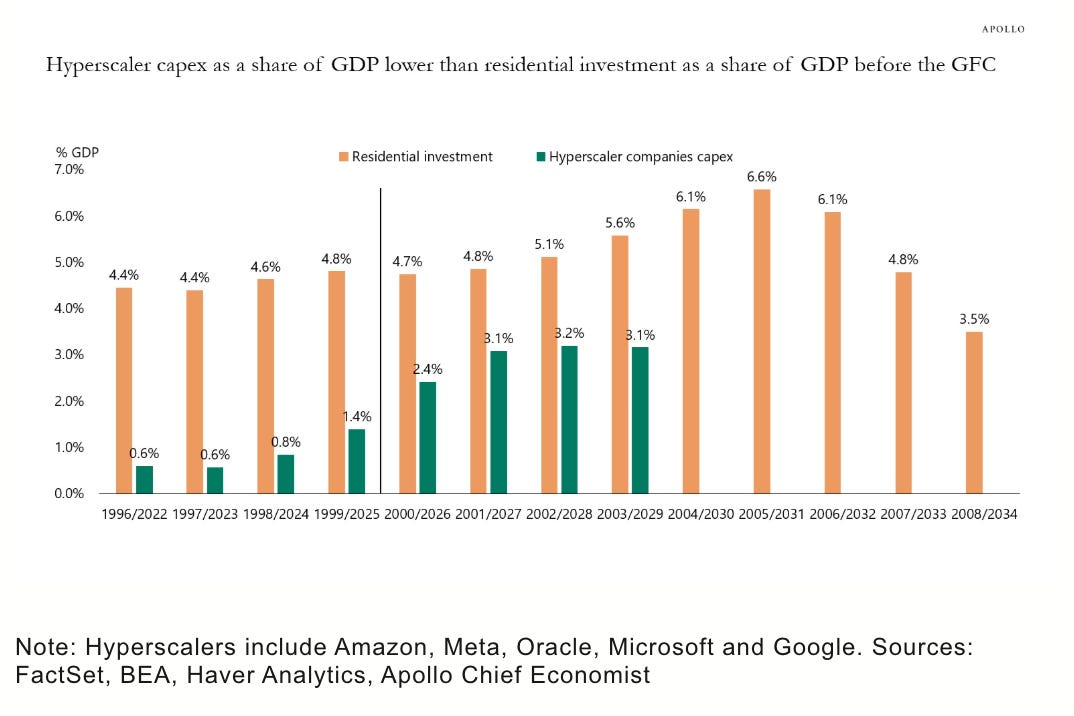
A Complicated Story - Chapter 1 - A dynamic economy increasingly powered by one engine: “The first chart below shows that the consensus expects hyperscaler capex to run at roughly 3% of GDP every year from 2027 to 2029, up from 0.3% of GDP in 2019 and 1.4% in 2025. The second chart shows that this is more than twice the peak of the telecom and fiber buildout of the late 1990s, which topped out at 1.2% of GDP in 2000 before collapsing and tipping the economy into the mildest post-war recession.The third chart shows that the data-center buildout is still less than half the size of the housing boom, which peaked at 6.6% of GDP in 2005. There are three ways to look at this data: 1. In level, the ongoing data-center buildout sits between the fiber and housing cycles: more than twice the fiber peak, less than half the housing peak. 2. In cumulative change, what matters is not the level of the share but how much it moves, because that is what adds to or subtracts from GDP. On the data in these charts, data-center capex rises 2.5 percentage points, from 0.6% of GDP in 2023 to 3.1% in 2027, against 0.4 percentage points for telecom in the late 1990s and 2.2 percentage points for housing from the mid-1990s to 2005. On this measure, the data-center buildout is the bigger capex cycle. 3. In speed, the contrast is sharper still, and it holds even when each cycle is measured over its own fastest stretch. Data-center capex adds 1.7 percentage points in just two years, from 1.4% of GDP in 2025 to 3.1% in 2027, or roughly 0.85 percentage points a year. Housing’s quickest phase, from 5.1% in 2002 to 6.6% in 2005, ran at 0.5 percentage points a year, and telecom’s at around 0.15. The AI cycle is building at close to twice the pace of the housing boom at its fastest. The bottom line is that the data-center buildout is smaller than housing in level but larger in the change in share of GDP, and faster than either previous cycle.The same arithmetic runs in reverse: housing’s unwind, from 6.2% of GDP in early 2006 to 3.0% by the end of 2008, is what made that recession severe, while telecom’s much smaller reversal produced the mildest one. A cycle that builds at 0.85 percentage points a year can unwind at a similar pace, and that, rather than the buildout itself, is the macro risk if AI demand disappoints.” - Apollo Research
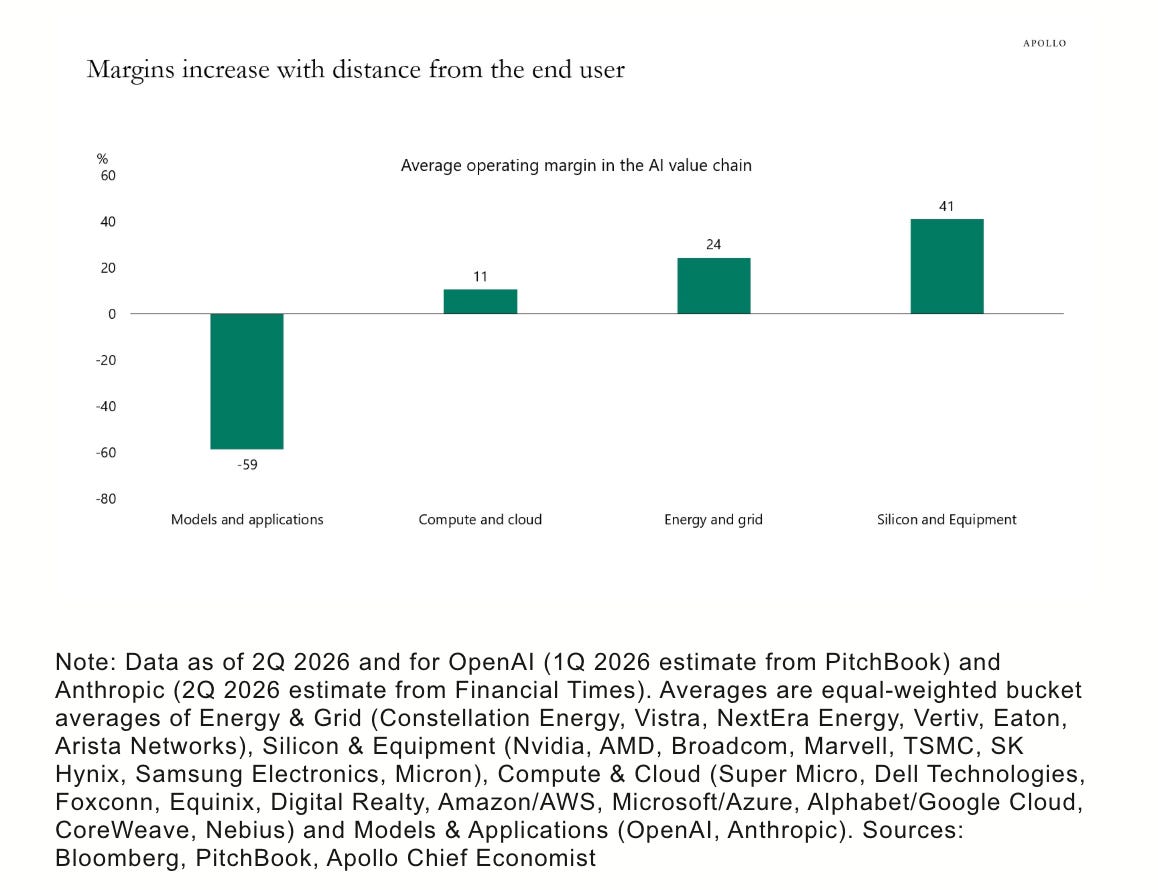
A Complicated Story - Chapter 2: Bridges to nowhere? - “In business, profit margins are frequently higher for the owner of the end-customer relationship. But that is not the case for AI. In AI, profit margins are higher the further you get from the end user, see chart below. This is important because it means the AI boom’s profits are currently being funded by investors rather than earned from customers. The upstream margins are real, but they are paid for out of capital raised by the layer losing money, not out of cash generated by end demand. That makes the 41% contingent on the -59% continuing to be financeable. The bottom line is that the most profitable part of the AI value chain depends on the least profitable part continuing to grow revenue or raise capital. Capital can bridge the gap for a while, but not indefinitely. And therein lies the risk: will the ROI show up for AI’s end customers fast enough to sustain the spending that is generating those upstream margins?” - Apollo Research
A Complicated Story - Chapter 3: The median voter is not buying into the hype: “Poll after poll shows that Americans are decisively opposed to data center construction in their area, and the issue is becoming more lopsided by the day:
An August 2025 survey conducted by Embold Research for Heatmap News…found that 43% of Americans said they would support the construction of a data center near them, while 42% were opposed…The latest survey, conducted last month, found a complete collapse among supporters: Today, just 21% said they support data center construction near them, while 71% are opposed — including 55% who say they are strongly opposed…A Gallup poll released in May showed the share of Americans who oppose the construction of data centers in their area, 71%, was higher than the zenith of the opposition to the construction of nuclear power plants, which topped out at 63% in 2001…A survey from Marquette Law School found 71% of voters nationwide said the costs of data centers outweigh the benefits, while 29% said the reverse. Voters said the development of AI is a bad thing for society, rather than a good thing, by a 65%-35% margin…A YouGov poll taken for The Economist found just 23% of voters who said the construction of data centers are good for the country, while 48% said they are bad for the country. That same poll found 60% opposed to building a new data center in their community. The opposition is incredibly bipartisan, with both Republicans and Democrats lining up to block data center construction. New York put a moratorium on data center construction in July, while Texas followed suit earlier this month. The big danger is that data center bans will choke off the main engine of U.S. growth, throwing a lot of Americans out of their jobs and putting a hole in Americans’ retirement savings.” - Noah Smith
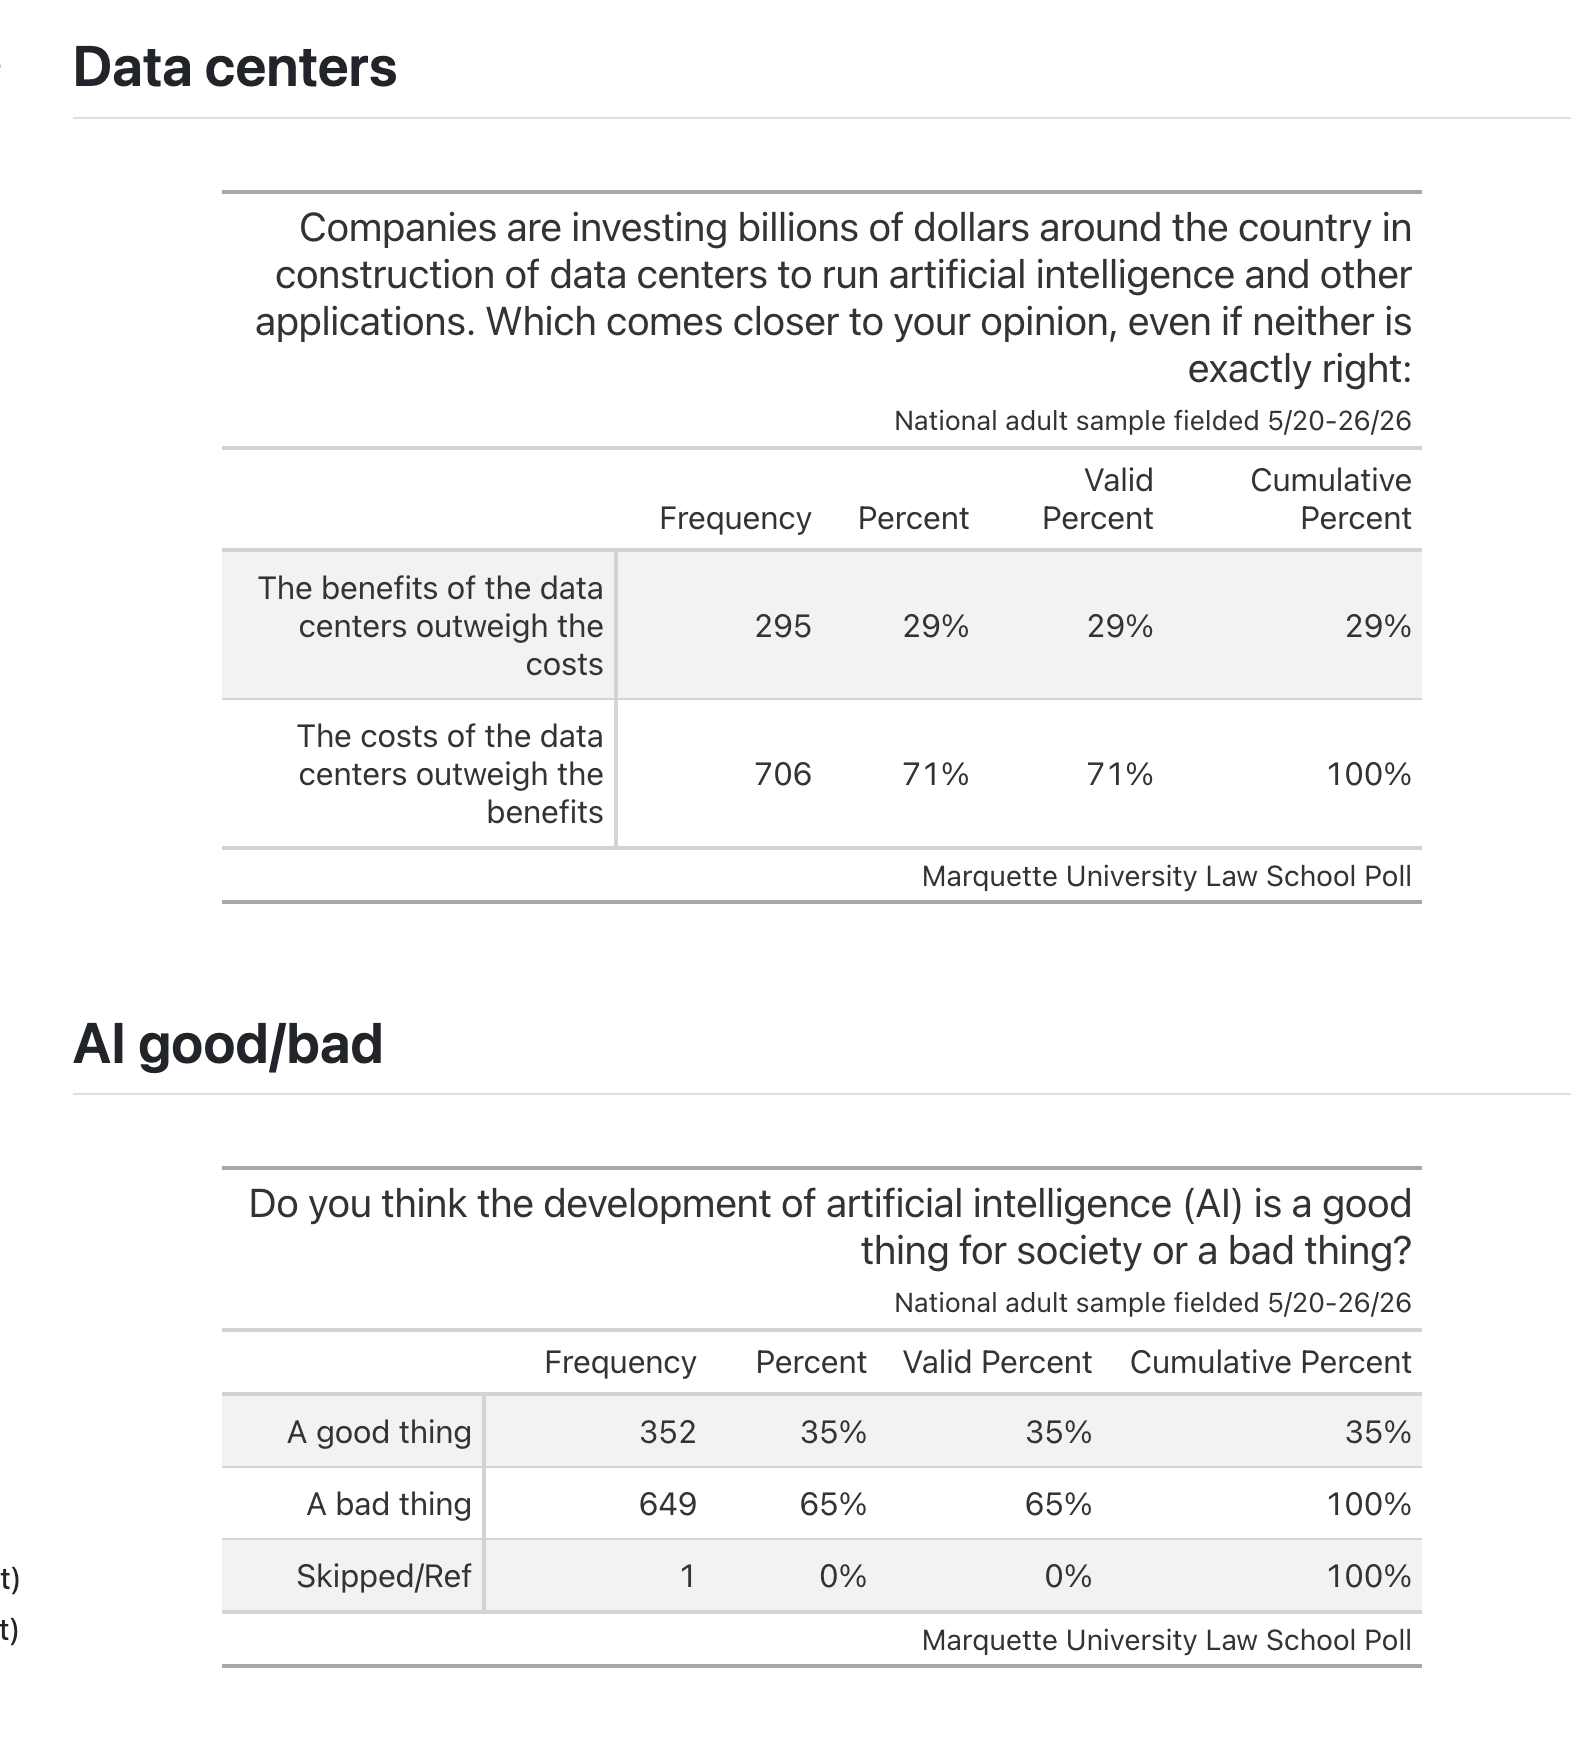
Learn more: https://law.marquette.edu/assets/community/poll/MLSPSC32/MLSPSC32Toplines_NationalIssues.html?utm_
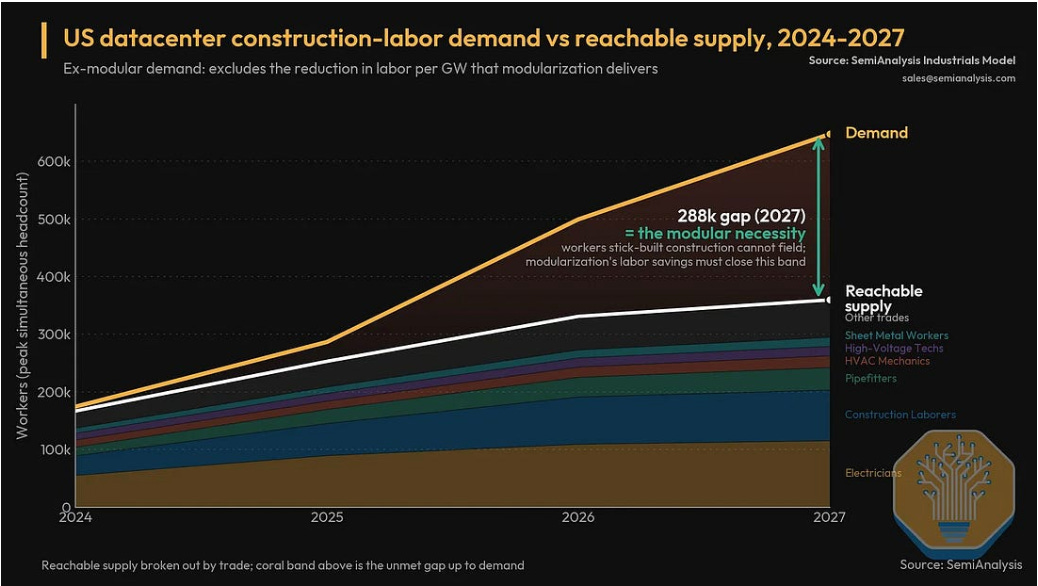
A Complicated Story - Chapter 4: Who will build it all? Skilled shortage. The data center build-out in the US is facing a skilled-trades gap of 288,000 workers to meet demand in 2027 if traditional construction methods continue. Higher premiums for these workers are increasing average earnings - if immigration continues to be constrained and the robots aren’t quite ready for construction work the US is looking at rising labor cost inflation which tends to be sticky.
2 If You Read One Thing Today - Make Sure it is This
My path crossed with Jim Bowery last week and it was an interesting conversation that I look forward to continuing - he hangs out with Markus Hutter of DeepMind and they collaborate on the interesting Hutter Prize project (Big idea, terrible website):
http://prize.hutter1.net/
- he was kind enough to share his essay below - it’s worth a read and a reread…
https://jimbowery.blogspot.com/2025/02/artificial-intelligence-in-nutshell.html
Some Takeaways
“Artificial Intelligence is the mathematical implementation of intelligence. A mathematical implementation is called an algorithm. In grade school, you learned to multiply two big numbers without a calculator. Remember? You learned an algorithm: A series of instructions to calculate a result. Back before computers there were humans called “computers” that followed complicated algorithms to compute things. Then computation was automated with electronics. Algorithms that instruct computers are usually called computer programs. To implement analgorithm nowadays, you almost always use a computer. Henceforth we’ll use “computer program” and “algorithm” interchangeably.”
“Intelligence is applied learning. You first go to school and then apply what you learned to do things of value.
Scientific research is societal-scale learning.
Technology development is societal-scale application of societal-scale learning.”
“Machine learning is the mathematical implementation of learning.
Applied machine learning is another way of defining “artificial intelligence”. But people too often get the cart before the horse, so to speak. Learning is hard. Science is hard. Research is hard. They are hard and not just because there is no immediate value. Even if you value learning for its own sake, it is still hard work. Worse, you’re never really “done”.
That’s why people fail to recognize that the most important thing in artificial intelligence is the mathematization of learning.
The mathematization of learning is called “Algorithmic Information Theory”. But almost no one in the “AI industry” is properly educated in Algorithmic Information Theory! We’ll get around to the strange and bizarre tale of why that is the case. But it isn’t because it is hard to learn what Algorithmic Information Theory is. That’s the easy part of understanding Artificial Intelligence.”
“AIT proves you should bet according to the predictions made by the shortest algorithm thatgenerates all past observations. That algorithm can then keep going to generate predictions of future observations. If you’ve heard of “generative AI” you now know what “generative” means.
Before AIT was mathematically proven, this rule about how to select the best algorithm to generate predictions was known as Occam’s Razor: The simplest explanation is the best.”
“This is the same problem human scientists face when asked to prove that their theory is the best theory possible. All a human scientist can do is appeal to Occam’s Razor or, if he’s a physicist, to Albert Einstein’s paraphrase of Occam’s Razor:
“A theory should be as simple as possible but no simpler.”
Of course, not even Einstein could prove that his theories were the simplest possible. All he could do was argue that they were simpler than other theories people had come up with.”
Now for the Big Reveal
The AI Industry has several “But The Dog Ate My Homework!” excuses for ignoring AIT:
Artificial scientists can’t prove a candidate algorithm is the shortest one possible. Never mind that not even Einstein could prove his theory was the best one possible.
AI experts are used to measuring error in statistical terms -- not in algorithmic terms. e.g. they can’t even begin to think about errors as what are called “program literals” such as “Error = 1” in the example above.
Critics of AIT say the language in which to express algorithms is “arbitrary” when, in fact, it is no more arbitrary than science’s choice of arithmetic to compute predictions.
They aren’t even aware that Algorithmic Information Theory rigorously formalizes science!
This last excuse is the most troubling of all. Popular “philosophers of science” like Popper and Kuhn spread ignorance of AIT right at the beginning of the explosion of data and computation, which continued year after year and continues after 70 years! Worse, radical social changes made AIT needed as a way to select which theory of social causation best fit the explosion of social data. If you want to know why the social sciences don’t have a principled criterion to select the best theory of the cause of social ills, ask Popper and Kuhn.
Given how divisive politics have become -- especially over the claim of who can rightfully don the authority of “science” -- perhaps debates over the “OUGHT” of artificial intelligence “alignment”ought to take a breather and get the “IS” of science right, starting with what science really is [1]. Then our decision-makers might have what they need. That brings us to the other half of Artificial Intelligence: Sequential Decision Theory.
The Other Half of AI: Sequential Decision Theory
Returning to our human friend, Joe for a moment. Let’s imbue Joe with a magic genie Scientist, named “Gene”.
Joe asks Gene, “What’s the shortest algorithm that generates a simulation of everything that has ever happened in the world?”
Gene says, “Uh, you don’t mean that literally do you, Joe?”
Joe says, “Of course not. I mean just give me a USB thumb drive that has The Algorithm.”
Gene hands Joe the thumb drive. Joe puts it in his laptop’s USB port. The laptop generates the history of the world right up to the present (it’s a magic laptop). And then it keeps on generatingfuture events faster than Reality unfolds. This lets Joe see the future. Joe flies to Las Vegas. He cleans out the casinos, buys a million Bitcoin with the winnings and flees Las Vegas with the mafia thugs hot on his tail. We’ll now return to our regularly scheduled lesson.
What you just witnessed was the application of a world model to get value. Nothing is remotely that perfect. But business schools of “management science” teach you about “Decision Trees”. The leaves have various values, like the billion dollars that Joe is after. The leaves also have negative values, like the mafia thugs catching up with Joe because Joe didn’t pay enough attention to his magic laptop to anticipate their moves. The forks in the branches are decisions,like the proverbial “fork in the road” where you must decide between the path taken and the pathnot taken.
But these forks have gambling odds associated with them. Nothing is certain.
You can’t see to the end of each fork in the road.
Your Genie and computer aren’t magic maps of the future. But you simulate the future with the shortest algorithm that your AIT meta-algorithm can come up with and the computer you have to explore the future scenarios, looking for the greatest expected value given all the risks of all the various paths.
So you provide something called a Sequential Decision Theory algorithm with your value systemotherwise called a utility function to which it can refer to decide which paths along the branches have the highest expected value given the sequence of gambling odds along each path and the pot of gold at the end of the path.
The Sequential Decision Theory algorithm uses the shortest algorithm that your AIT algorithm could come up with to calculate the gambling odds for each decision along each path.
These gambling odds are called the “Algorithmic Probabilities” of your decision tree.”
3 Consequential Thinking about Consequential Matters
Steve Hsu takes a hard look at AI Revenues, Circular Demand, and the Capex Hurdle with some support by ChatGPT - as outlined in the Complicate Story in section 1, its Consequential Thinking about Consequential Matters - Go come to your own conclusions here:

Some Takeaways…
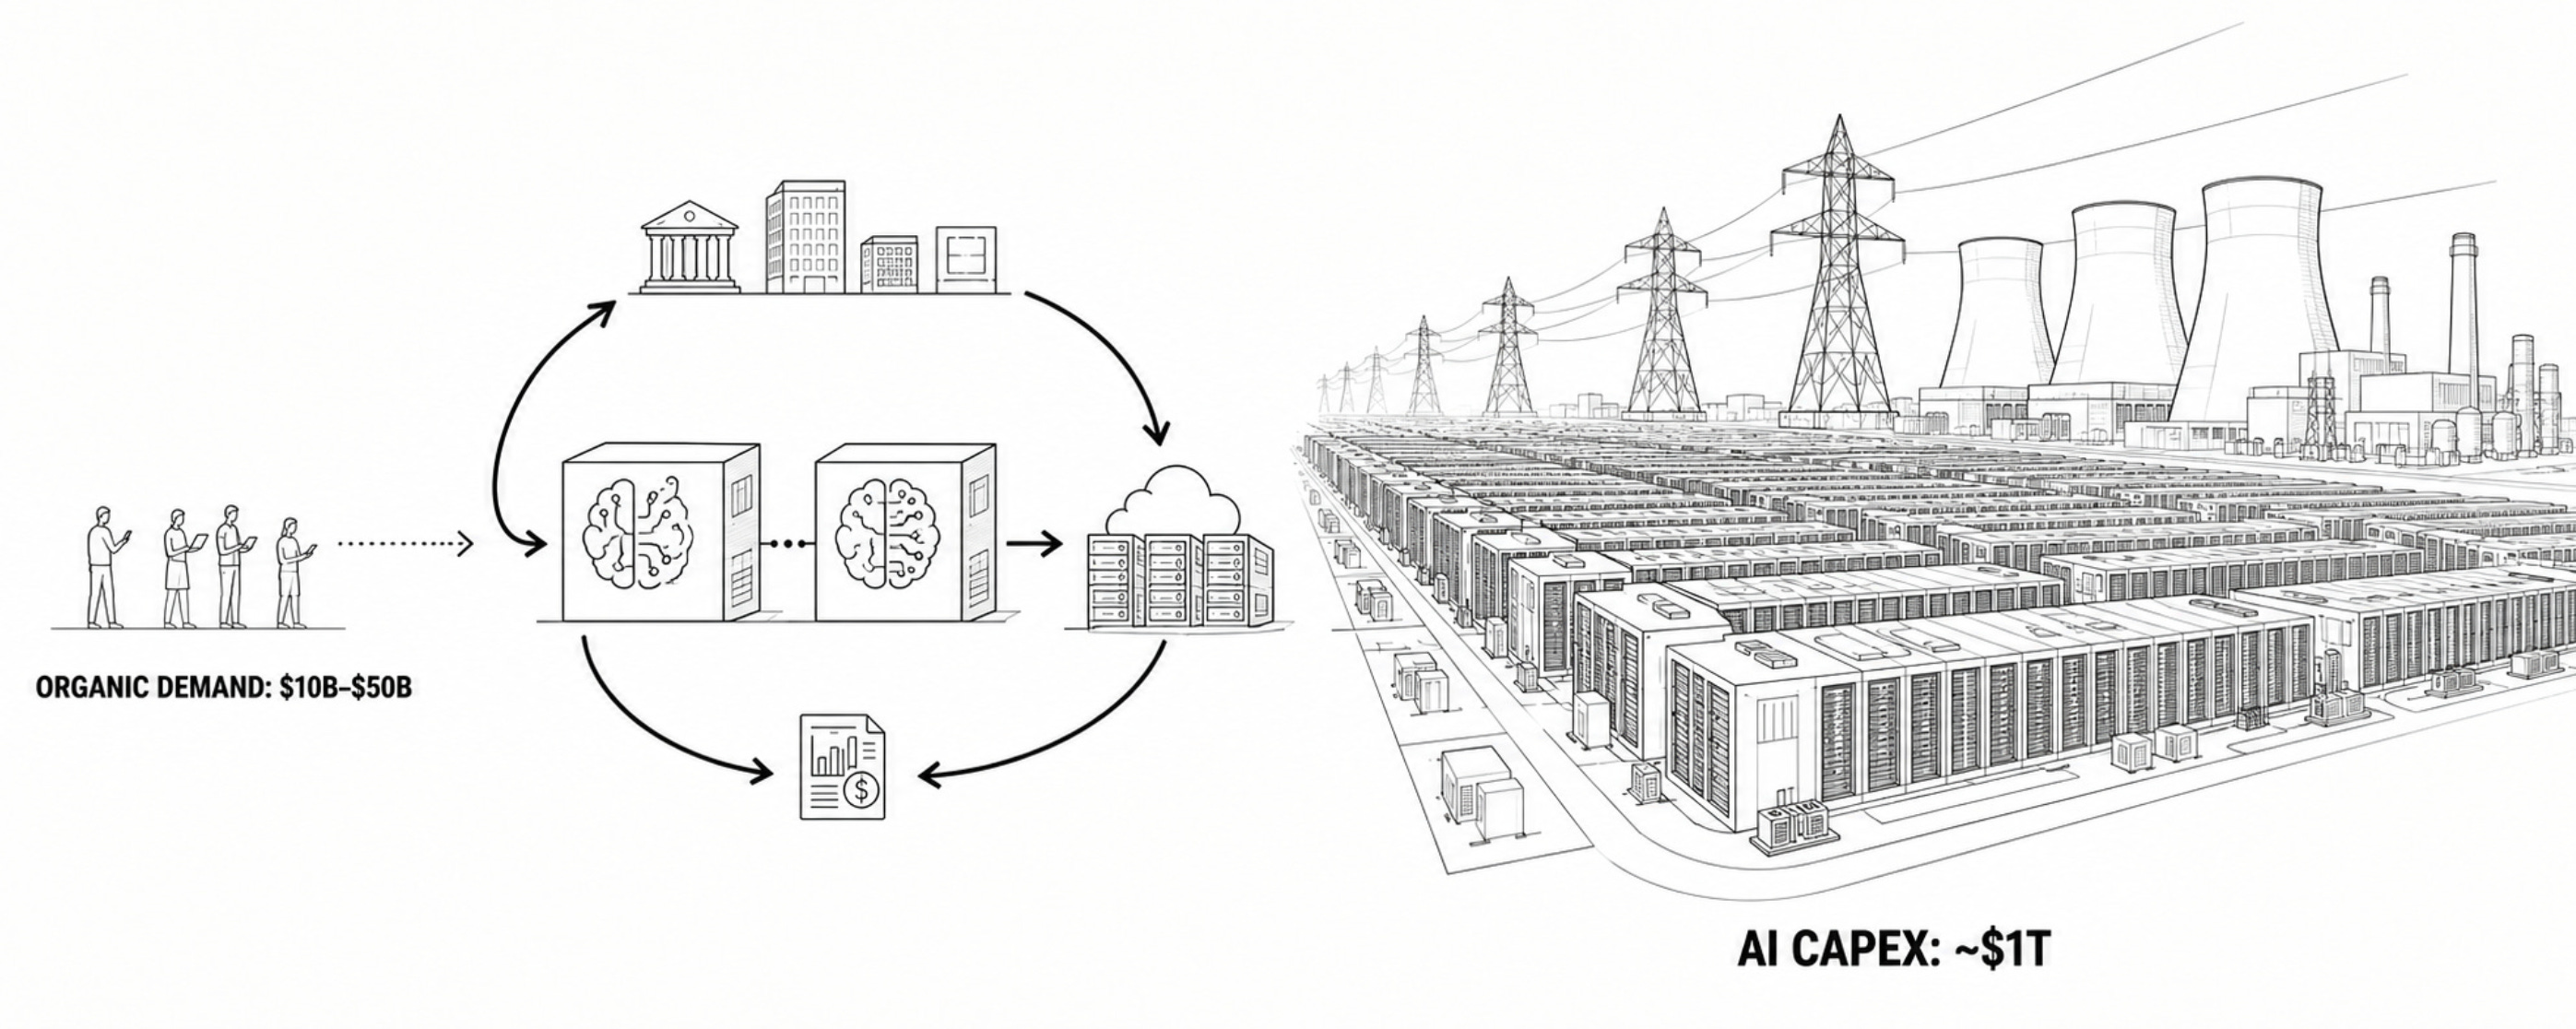
“…current AI revenue is heavily concentrated in OpenAI and Anthropic, while much of those companies’ spending is financed by investors rather than by operating profits. The amount of genuinely organic demand—money ultimately coming from consumers and established, cash-generating companies—appears to be only of order $10 billion. A more detailed reconstruction might produce $30–50 billion rather than exactly $10 billion, but these are consistent order-of-magnitude estimates.
Either is tiny compared with the hundreds of billions being invested annually in AI infrastructure.
The concentration claim is best documented at Microsoft. Its FY2026 filing reports $24.1 billion of revenue from OpenAI, including revenue-sharing payments, against analyst estimates of roughly $34.5 billion in total Microsoft AI revenue. That implies approximately 70% dependence on OpenAI. Microsoft also reported $6 billion of OpenAI accounts receivable at year-end.
For AWS, analyst estimates put OpenAI and Anthropic at roughly 59–73% of AI revenue, although Amazon does not disclose customer concentration. Amazon has said its AI business now exceeds a $25 billion annual revenue run rate, while Anthropic has committed more than $100 billion to AWS over ten years.
Google is less transparent. UBS estimates reportedly imply that OpenAI and Anthropic constitute about 28% of total Google Cloud revenue in 2026 and nearly half in 2027. Because Google Cloud also includes conventional computing, storage and software, the two labs could plausibly represent most of its specifically AI-related revenue, but the “70%” figure is inferred rather than disclosed. Google Cloud revenue nevertheless grew 82% in Q2, driven primarily by AI infrastructure and enterprise AI services.
The crucial point is that revenue at successive layers of the AI stack cannot be added together as independent demand.
A company may pay Anthropic for Claude usage; Anthropic then pays AWS or Google for the compute. The same external dollar appears first as model-company revenue and again as cloud revenue. Moreover, when Anthropic or OpenAI spends more on compute than it receives from customers, the difference is supplied by newly raised capital. OpenAI, for example, reports about $2 billion in monthly revenue but raised $122 billion at an $852 billion valuation in March. Anthropic reports a $47 billion revenue run rate but simultaneously raised $65 billion at a $965 billion valuation.
After removing double counting and heavily discounting AI consumption by loss-making, venture-funded startups, a reasonable estimate of current final demand is approximately:
$15–20 billion from OpenAI consumers and established enterprises;
$10–20 billion from Anthropic consumers and established enterprises;
perhaps another $5–10 billion from other direct products and non-lab enterprise AI consumption.
That gives roughly $30–50 billion of annualized organic demand. But this remains of order ~$10B, precisely the scale asserted in the original post. Indeed, given the uncertainty surrounding Anthropic’s rapidly annualized “run-rate” metric and the startup share of enterprise API consumption, $10 billion is a defensible lower-end estimate. Reuters has noted the striking gap between Anthropic’s claimed annualized run rate and the much smaller amount of revenue it had actually booked cumulatively.
Against this ~$10B organic revenue base, the infrastructure buildout is ~$trillion. Amazon, Microsoft, Alphabet and Meta are on course to spend roughly $700 billion in 2026, with Oracle and other providers pushing the total higher. Not all of this is AI-related, but approximately $450–600 billion probably is.
The spending is already consuming most of the hyperscalers’ cash generation.
Amazon’s trailing free cash flow was negative $7.6 billion; Meta produced only $784 million of Q2 free cash flow after $31.1 billion of capex; and Alphabet reported negative $5.9 billion of Q2 free cash flow. Microsoft remains strongly cash-generative, but its cash capex nearly doubled to $115.9 billion, with another $24.6 billion of infrastructure obtained through finance leases. Current net income figures are also flattered by paper gains: Amazon’s Q2 earnings included a $53.4 billion pre-tax gain primarily on Anthropic, while Alphabet recorded a $77.1 billion after-tax gain on equity securities.
A simple capital-recovery calculation illustrates the hurdle. If the industry invests $450–550 billion annually in AI infrastructure from 2026 through 2029, it will create roughly $1.8–2.2 trillion of installed capital. Assuming a five-year blended economic life, a 9% required return and 40–60% cash contribution margins, that infrastructure ultimately needs approximately $700 billion to $1.3 trillion of annual revenue. A central estimate is about $1 trillion.
Growing an organic base of $30–50 billion to $700 billion–$1.1 trillion by 2030 requires approximately 90–120% annual growth.
In other words, organic AI spending must roughly double every year for another four years. The private valuations of OpenAI and Anthropic alone require somewhat less but still extraordinary growth: their combined $1.8 trillion valuation plausibly requires $300–500 billion of annual revenue by 2030, implying roughly 60–90% annual organic growth from the estimated present base.
Thus, the more detailed analysis reinforces the original post. Whether present organic AI revenue is labeled $10 billion, $30 billion or even $50 billion does not materially change the conclusion.
The industry is attempting to support an ~$trillion capital base with an ~$10B final-demand base. The capex and current valuations can make sense—but only if organic use approximately doubles every year, customer concentration falls, and margins improve despite rapidly declining compute prices.
If organic demand grows at a still-impressive 50% annually, a $40 billion base reaches only about $200 billion by 2030. That would support several very valuable AI businesses, but not the infrastructure currently being built.
In that scenario, the likely outcome is substantial excess capacity, collapsing compute prices, asset impairments and valuation compression—especially for model labs, Nvidia, neoclouds and leveraged data-center projects.”
4 Big Ideas
IFI Claims Patent Services takes a deep dive into patent trends around AI in all it’s emergent forms - plenty of good insights and big ideas - go explore it here in full:
https://www.ificlaims.com/news/ifi-insights-inventing-ai/?utm_
Some Takeaways
“Three-plus years into the release of ChatGPT, this AI revolution—encompassing everything from cloud computing, data centers, and robotics in addition to the staggering progression of analytics, content creation, and inference—just keeps ‘gaining momentum.”
Patents in the AI Universe
In the few years since generative AI burst upon the scene, the entire AI landscape has progressed in both sweeping and narrow ways. The AI advancement has generated both complexity and depth as new phases of AI form from previous achievements. Of the 209,518 patent applications in artificial intelligence filed around the globe in 2025, some 23% of those are directly related to generative AI—the kind of AI that uses large language models on massive pools of data in response to human triggers. These sophisticated algorithms then create original text, images, video, and other human-like output.
Within the AI sphere, 9% of those are taken up by yet another variety that has companies and investors looking for onramps: agentic AI, which performs even more independently than GenAI. AI agents can ideate, determine, and execute complex workflows to achieve tasks. The agentic imprint is small but increasing, taking up 9% of global applications this year compared to 5% from our previous study.
For just U.S. applications in 2025, the agentic AI frenzy is more pronounced. GenAI covers 16% of the AI patent domain, about the same as before. But agentic AI now comprises 15%, up from just 7% in IFI’s previous findings.”
“The past decade has seen a surge of invention around artificial intelligence.
Global AI grants have risen at a compound annual rate of 35%, while applications have grown by 29%. For U.S. patents, the trendline was quite steep from 2018 to 2023, but has leveled off over the past couple years in both grants and applications. Generative AI has posted strong and steady patent gains on both fronts though.
Around the world, grants have expanded by 54% on an annual basis, while applications escalated 44%. Growth is remarkable too in the U.S. with GenAI grants progressing 31% as applications increased 29%. As for agentic AI? The curve also rises: global grants turned up 42%, with applications up 43%. In the U.S., grants rose 27%, as applications climbed 22%.
Drilling down a little more on applications, notice how sharp the incline is in the last two years, a signal of intense interest in protecting inventions around agentic technology. Worldwide, agentic applications rocketed 59% over the past two years, while in the U.S., they’ve risen by 40%.”
Essential Technologies
One of the biggest misinterpretations around inventions is that a patent protects something that is utterly new. But inventions stand on the shoulders of previous inventions, which are, in turn, buttressed by patent technologies that have been cultivated for decades.
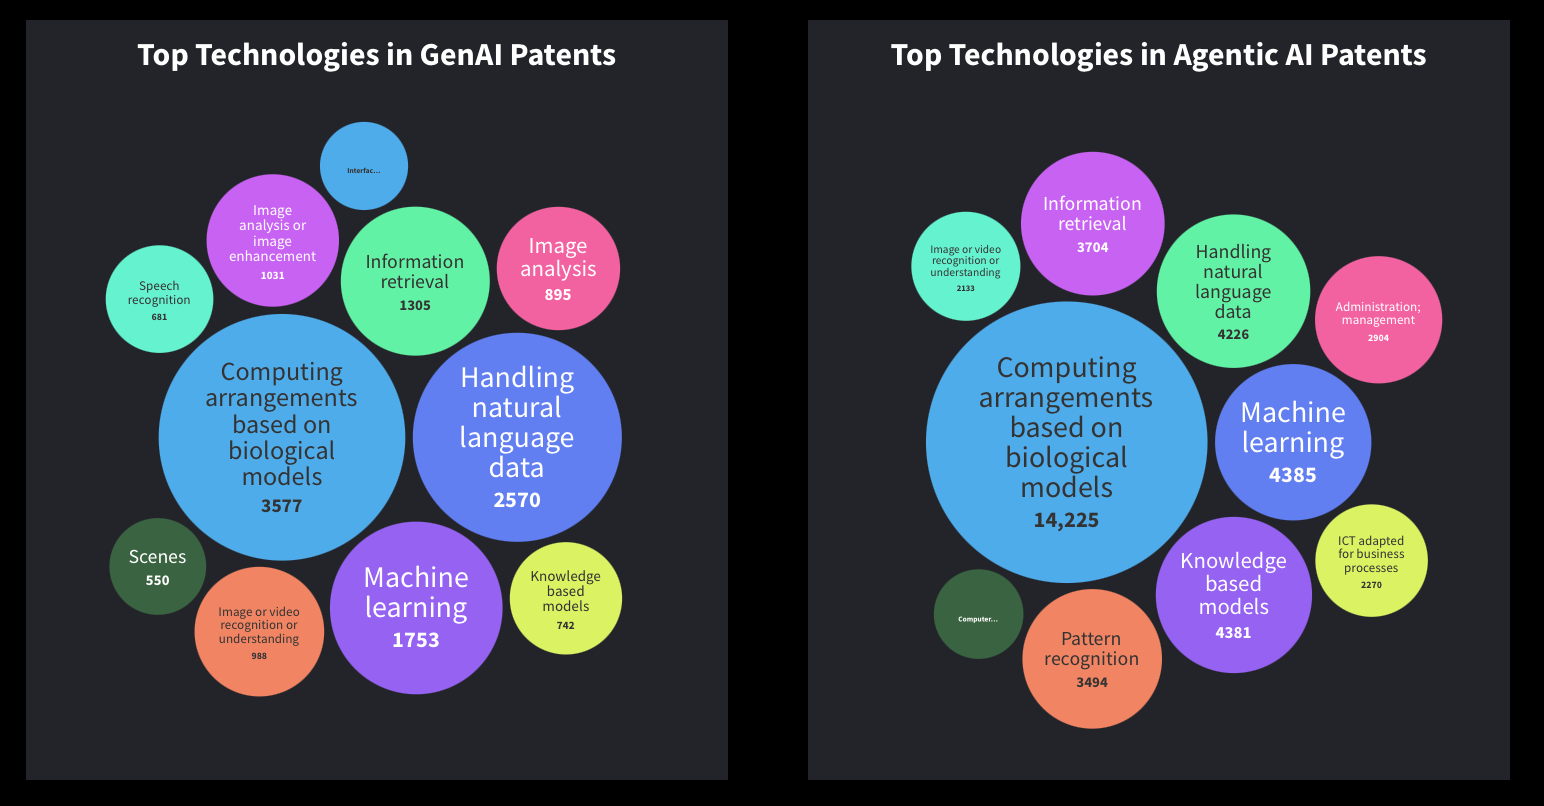
Generative AI has certainly bowled the world over. But the underlying technologies upon which GenAI inventions are built have been hanging around for some time now: machine learning, image analysis, information retrieval, handling natural language data. It’s just that they all came together in a way that created this new technological wonder.
The patent subclass key to GenAI comes from the field of life sciences; it’s called “computing arrangements based on biological models,” and has appeared on IFI CLAIMS’ annual list of Top 10 Fastest Growing Technologies for a number of years as GenAI was quietly developing behind the scenes. GenAI patents rely heavily on this class because it makes use of deep learning (especially convolutional neural networks), a technology furthering computing that mimics human reasoning.
Agentic AI leans heavily on many of the same technologies; in fact “computing arrangements based on biological models” looms even larger in this area. “Administration; management” is an essential technology for agentic AI—perhaps for all the office work our AI agents are expected to perform for us humans?”
Qualified AI Applicants
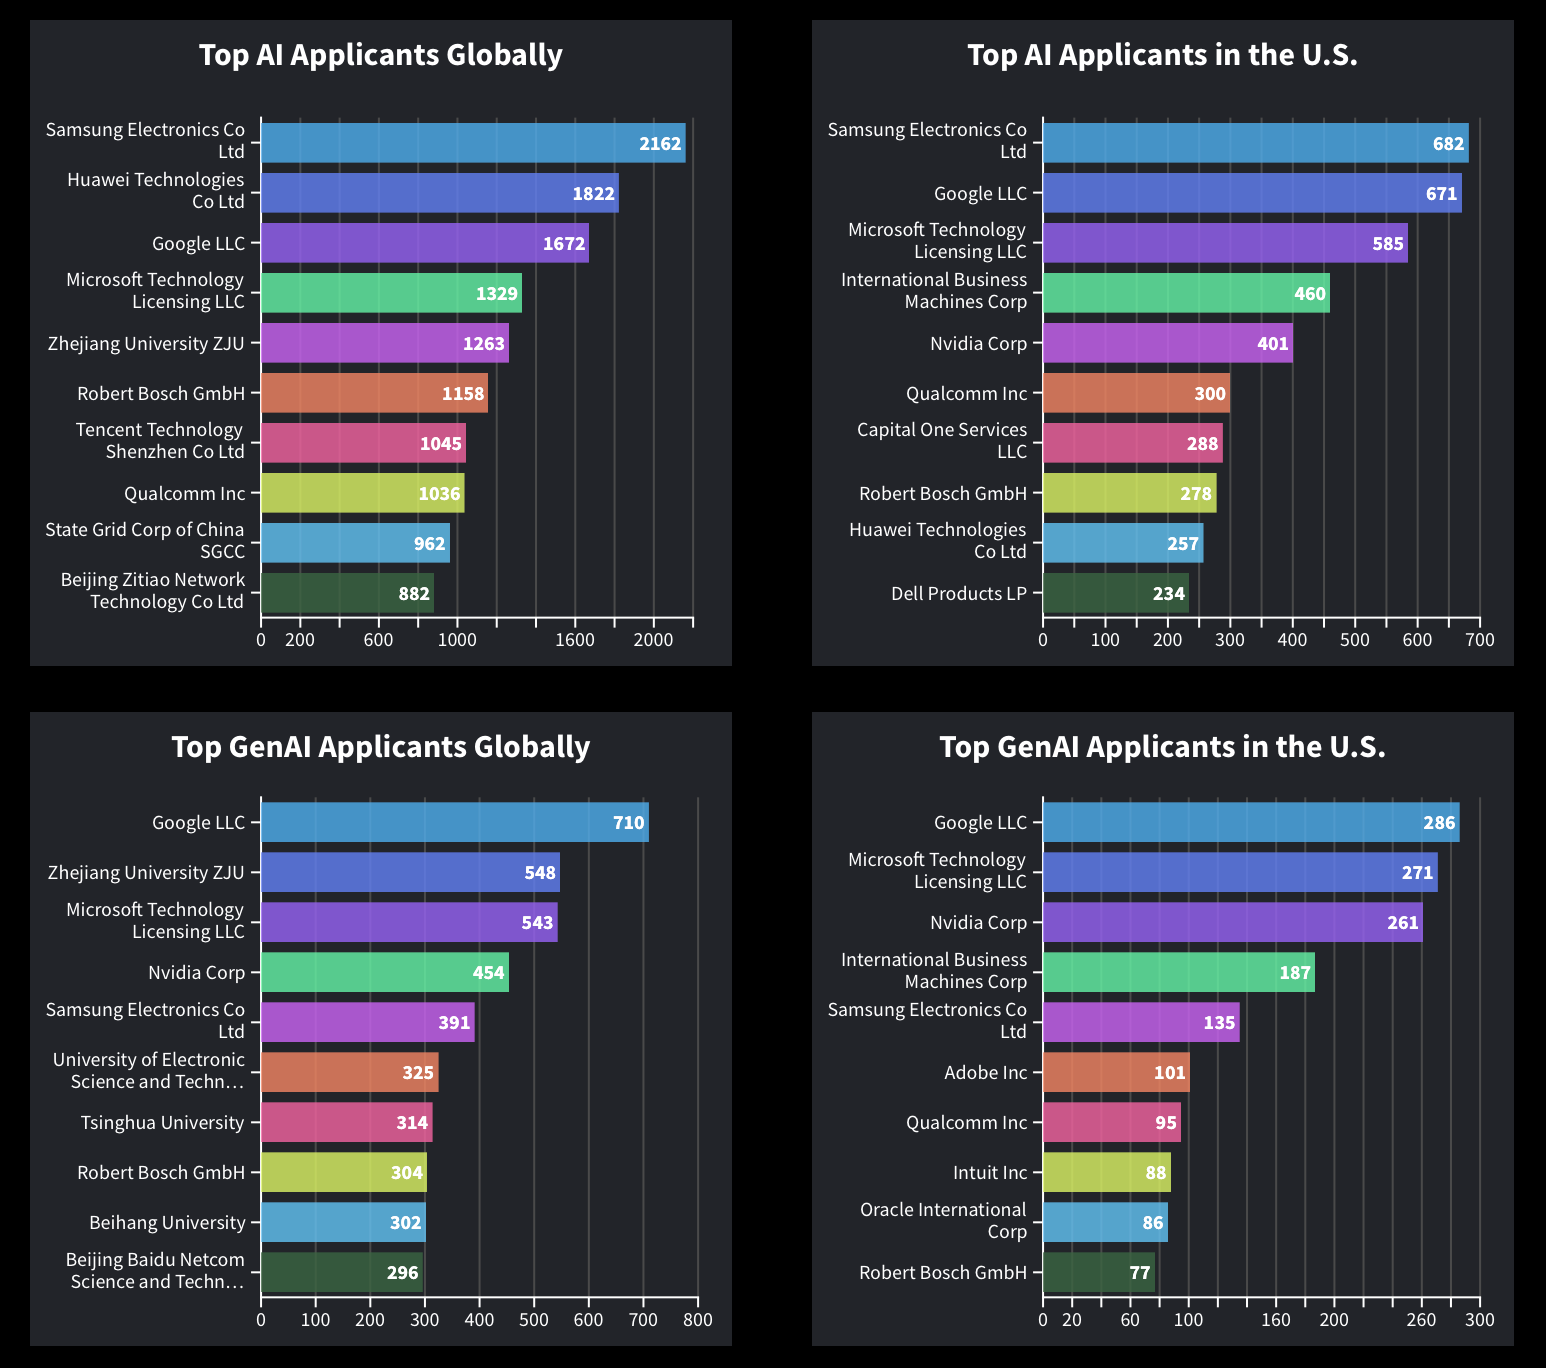
When it comes to the overall area of artificial intelligence, Samsung is the company that applied for the most patents worldwide in 2025 with 2162 filings, followed by Huawei (1822) and Google (1672). When looking at just U.S. filings, Samsung also places first with 682 applications, followed by Google (671), and Microsoft (585). Other stalwarts at the top include IBM (460), Nvidia (401), and Qualcomm (300).
Narrowing the field to generative AI patent applications, Google takes top billing both globally and in the U.S., compared to Samsung’s fifth-place showing in both listings. Microsoft and Nvidia are the other companies inventing robustly in this space. One Google patent filed last year in GenAI is this one for a generative model routing system. As for Microsoft, the company put forth this patent in 2025 for a fine-tuning simulator for machine learning models. And here is an Nvidia patent for generating a response in an AI system after an image or video input. All are still pending.
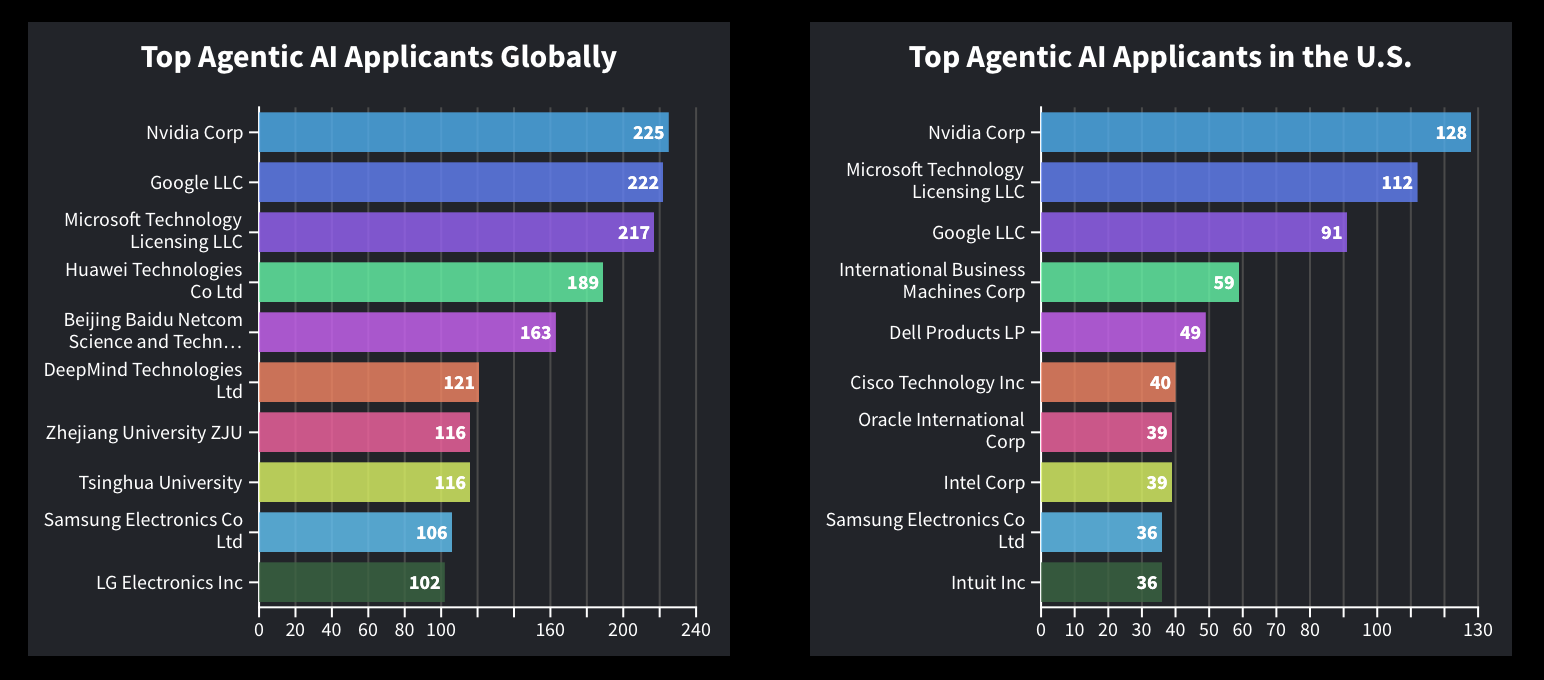
Google is also a prime patenter in the field of agentic AI. But it doesn’t take the top spot. That goes to Nvidia, the Wall Street darling of the AI boom, which is first in both global and U.S. agentic patents, with 225 and 128 applications, respectively. Google comes in second worldwide and third stateside (222 and 91), while Microsoft rounds out the top three in both categories (217 and 112).This recent application from Nvidia for an interactive agent platform is still pending. Here’s another pending patent, this time from Google for a conversational AI agent. And this Microsoft patent uses agents to determine whether or not certain data is malicious. It was granted this past April.
The AI Contenders
AI is a giant sandbox, and every company seems to be playing in it. But we wanted to take a look at just a handful for the moment—the ones garnering more of the attention in the business press and from investors.
Not surprisingly, big company competitors Google, Microsoft, and Nvidia are way out in front when it comes to filing patents globally and in the U.S. But disruptors OpenAI and Anthropic, both on the cusp of going public sometime in the near future, are also protecting their inventions. Anthropic filed 8 patents worldwide and 7 with the USPTO in 2025. One such example is this onefor training agents to automate tasks, filed last year. For its part, OpenAI is also racking up patents, with 35 around the world and 27 in the U.S. This is quite a jump from some two years agowhen IFI found fewer than five patents from the pioneering GenAI company. Last year, the company pledged to use its patents only for defensive purposes: “We recognize the role that patents play in the technology landscape, and commit to using our patents in a way that supports innovation,” according to OpenAI’s statement on its approach to patents. Here is a recent OpenAI application for a generative response system using chain-of-thought logic.
Deepseek, a Chinese model that shook the stock market in early 2025—Nvidia’s stock price suffered a $600 billion loss in one day—when its LLM performed as well as ChatGPT at a fraction of the investment, doesn’t hold any patents related to its technology. (Deepseek is preparing to list in Shanghai sometime next year.)
And xAI (a subsidiary of SpaceX, which recently debuted in a historic public offering that minted Elon Musk as the world’s first trillionaire), holds no patents that we could find. This is not a shock. Musk has long preferred open source and trade secrets over patents, which he sees as a tool to suppress progress. “Patents are for the weak,” he famously told Jay Leno a few years ago during a tour of Starbase in Texas. “They’re used like landmines in warfare,” he went on. “They don’t actually help advance things; they just stop others from following you.”
AI Titans and Their Technologies
The Cooperative Patent Classification (CPC) codes are hierarchical tags that label and organize technologies contained within an invention. Monitoring the increase (or decrease) in CPC codes overall or by company can signal to the market what technologies are gaining traction or attracting interest—and which entities are in hot pursuit of them.
In breaking down our narrow group of companies by the main technologies that are contained in their AI patents, we can see, for instance, that computing arrangements based on biological models (G06N 3) is, by far, the main covered area by most of the top AI applicants. Within this class, Google patents specifically on neural networks (G06N 3/08) and combinations of networks (G06N 3/045). Google’s other top classifications include language technologies (G06F 40) and machine learning (G06N 20). One of Nvidia’s top technology areas is image and video recognition, particularly pattern recognition through combinations of neural networks (G06V 10/82).
ChatGPT creator OpenAI is mostly pursuing language technologies (G06F 40), specifically translation of natural language (G06F 40/40) and lexical analysis (G06F 40/284). Its rival Anthropic also covers lexical analysis and most recently, image and video recognition using neural networks (same as Wall Street superstar Nvidia).
As for Chinese companies Alibaba and Baidu? Apart from covering the main AI area (G06N 3) they are mostly focused on information retrieval (G06F 16).
Why is this important to understand? Studying the direction of CPC codes provides a layer of nuance when trying to predict industry trends or eventual winners in a market. Much has been written about the rivalry between OpenAI and Anthropic—and that competition will continue to play out in the years to come. Both companies are expected to go public soon and their financials will be scrutinized and compared as heavily as their LLM models.
As investors decide how to allocate their dollars between all these AI companies, seeing where their CPC codes overlap and diverge can help identify the company’s potential strengths and weaknesses and pinpoint their most important technological hotbeds.”
5 Big thinking
Christina Lennartz explores the power of systems thinking as seen through the design lens - plenty of good perspectives to ponder in a broader way - go do it here:
Some Takeaways
“Humans are not isolated individuals acting in a vacuum. They are shaped by the systems they live in – families, teams, organizations, cultures, economies. Each person’s needs, behaviors, and decisions are influenced by a complex web of visible and invisible forces. So if we’re serious about designing for people, we also need to design for the systems that surround them. That’s where Systems Thinking comes in.”
“Design Thinking gives us powerful tools to zoom into the user’s experience – to empathize, ideate, prototype, and test. But sometimes, in our effort to improve the “tree,” we lose sight of the “forest.” In German, there’s a phrase: “Man sieht den Wald vor lauter Bäumen nicht” – we can’t see the forest for the trees.
Systems Thinking invites us to step back and view the entire ecosystem. It helps us understand how structures, relationships, policies, mental models, and cultural norms interact to influence people’s behavior. It’s not about rushing to fix a problem — it’s about learning to sit with it, observe it, and explore its deeper causes.”
“In short, Systems Thinking is essential for tackling wicked problems — the messy, complex, and evolving challenges that don’t have clear boundaries or easy fixes.”
“Systems Thinking becomes especially valuable when:
Problems persist despite well-designed solutions.
Multiple stakeholders are involved, often with conflicting goals.
Change efforts stall due to invisible resistance or misalignment.
Solutions improve one area while unintentionally creating new issues elsewhere.”
Systems Thinking isn’t just a toolkit. It’s a mindset – one that calls for a different way of seeing, thinking, and working. It asks us to resist the urge to jump to solutions and instead slow down to understand. It’s about noticing patterns, not just problems; connections, not just components.
This mindset requires us to:
Zoom out before zooming in. To see the broader system and how parts influence one another.
Hold multiple perspectives at once. To recognize that different stakeholders may see the same problem in vastly different ways – and all may be valid.
Look beyond symptoms. To uncover deeper root causes, structures, and feedback loops that perpetuate the current state.
Challenge assumptions and mental models. To understand how beliefs, norms, and ways of working shape system behavior, and how they might be redesigned.
Perhaps most importantly, it teaches us that meaningful change often starts below the surface. It’s not just about shifting policies or redesigning processes. Real transformation comes when we explore—and shift—the mindsets and relationships that uphold the system in the first place.”
“…we often describe Systems Thinking as the wide-angle lens that complements Design Thinking’s close-up focus. Both are human-centered. Both are creative, iterative, and oriented toward meaningful change. But they differ in how they approach complexity — and when used together, they amplify each other.”
“In practice, we use Systems Thinking to:
Outcomes:
Frame the problem more holistically before jumping into ideation.
Surface the root causes that might be invisible in user interviews alone.
Align stakeholders by making hidden dynamics visible.
Design interventions not just for the front stage, but for the backstage — policies, structures, incentives, and culture.
When we blend both approaches, we not only design better services — we also build better foundations for change.”
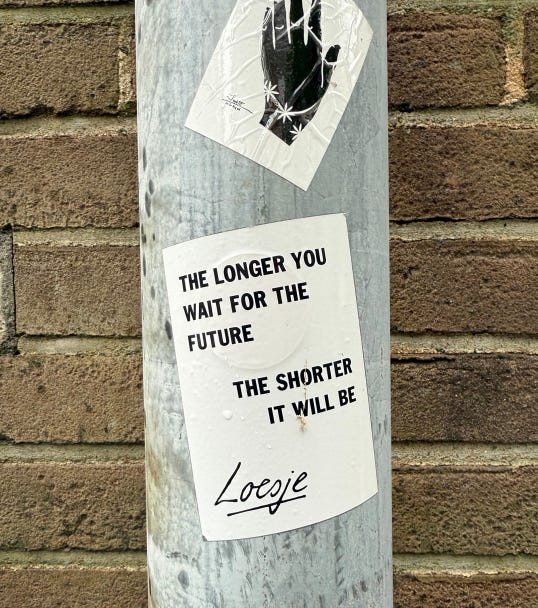
6 The Longer You Wait
Have a Great weekend when You get to that stage,
Sune